
An AI software development service turns a model into an application a business can actually use, which is a different problem from training the model itself. Many AI projects demo well and never ship, because the hard part is the architecture, data and deployment around the model, not the model alone. Building an AI application means wiring data, models, retrieval and guardrails into a system that is reliable, governed and maintainable. This guide walks through the architecture of an AI application, how to get the data right and the steps to take it from idea to production.
Building an AI application means designing the data, model, retrieval and application layers into one governed system, then deploying and monitoring it, so a model becomes a reliable product rather than a prototype.
The Architecture of an AI Application
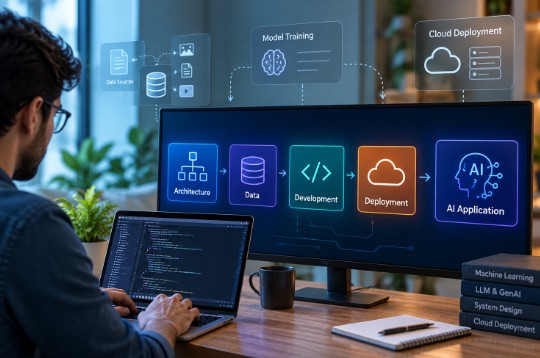
An AI application is a stack of layers, each with a defined job, not a single model with a wrapper. Treating them as one connected system is what separates a product from a demo. The layers below are what a production AI application usually includes.
- Data layer: the governed, connected data the application reads, including documents and records prepared for AI use.
- Model layer: the model or models that reason over inputs, chosen and sized for the specific task.
- Retrieval layer: the search and grounding that feed the model relevant, current context from your own data at query time.
- Orchestration layer: the logic that connects the model to tools, data and systems so it can complete multi-step tasks.
- Application layer: the interface and workflow where users interact with the AI and act on its output.
- Guardrails and governance: the access control, oversight and monitoring that keep the system safe and accountable.
The layer teams most often underbuild is retrieval and data, not the model. A strong model on weak, ungoverned data produces confident, wrong answers, which is why the data layer deserves as much attention as the model.
Getting the Data Right
An AI application is only as reliable as the data beneath it. The model does not know your business, so the data and retrieval layers are what ground it in reality. In practice, that means connecting and cleaning the sources, then using retrieval so the model answers from trusted content rather than from memory. Grounding an answer in your own documents, with a traceable source, is what cuts hallucination and makes the output auditable. Governance belongs here too, so the application reads only the data a given user is allowed to see. A capable custom AI development company such as Successive Digital treats this data foundation as the first build, not an afterthought once the model is chosen.
Deployment and Operations
Shipping an AI application is the start of its real life, not the end of the project. Models drift, data changes and usage grows, so the system needs operations built for it. The practices below are what keep an AI application reliable after launch.
- Monitoring and evaluation: track accuracy, latency and drift in production, since quality is not fixed at deployment.
- Human oversight: keep people on high-impact decisions, with the AI handling scale rather than final authority.
- Cost control: manage the cost of running models, which can exceed the cost of building the application if left unchecked.
- Security and access: enforce who and what each part of the system can reach, so the application cannot overreach its data.
These operations are what turn a working build into a dependable product. An AI application left unmonitored degrades quietly, often without anyone noticing until a decision goes wrong.
A Step-by-Step Path to Production
Building an AI application works as a sequence, since each step depends on the one before. Skipping ahead to the model is the usual way projects stall. The steps below sequence the work from use case to a deployed system.
- Define the use case: pick one high-value problem with a clear outcome, rather than a broad ambition to add AI.
- Prepare the data: connect, clean and govern the data and documents the application will rely on.
- Choose and size the model: match the model to the task, using a smaller model where it is enough to control cost and latency.
- Build retrieval and grounding: ground the model in your own data so answers are relevant and traceable.
- Integrate and add guardrails: connect the application to systems and add oversight, access control and monitoring.
- Test, deploy and monitor: validate against real cases, deploy to a pilot and watch it in production before scaling.
Following the order keeps the foundation sound as the application grows. Teams that build data and retrieval before scaling end up with ai development solutions that stay reliable, rather than a prototype that works only in a demo.
One more decision shapes the whole build: how much to buy and how much to engineer. Foundation models, vector databases and orchestration frameworks are bought rather than built, while the data pipelines, retrieval logic and guardrails specific to the business are engineered. Getting that split right keeps the project focused on what actually sets the application apart, instead of rebuilding what already exists off the shelf.
Conclusion
Building an AI application is a systems problem, not a model problem. The architecture, the data and the deployment around the model decide whether it becomes a product a business can trust or a demo that never ships. Getting the data and retrieval right, adding guardrails and building operations for the long run is what moves an AI application into production and keeps it there. An experienced AI software development service, such as the work Successive Digital delivers, treats the data foundation and governance as seriously as the model, which is what separates AI that ships from AI that stalls.